Dataset Versioning for Computer Vision and Experiment Tracking
 Sergey SychUpdated
Dataset versioning for computer vision: compare DVC, Git LFS and Supervisely, and link dataset versions to experiments, models and benchmark reports.

Dataset versioning for computer vision means saving every state of your images and annotations, so you can restore it, compare it and trace which version trained which model. You can do it with DVC, Git LFS, or the built-in data versioning and experiment tracking in Supervisely.
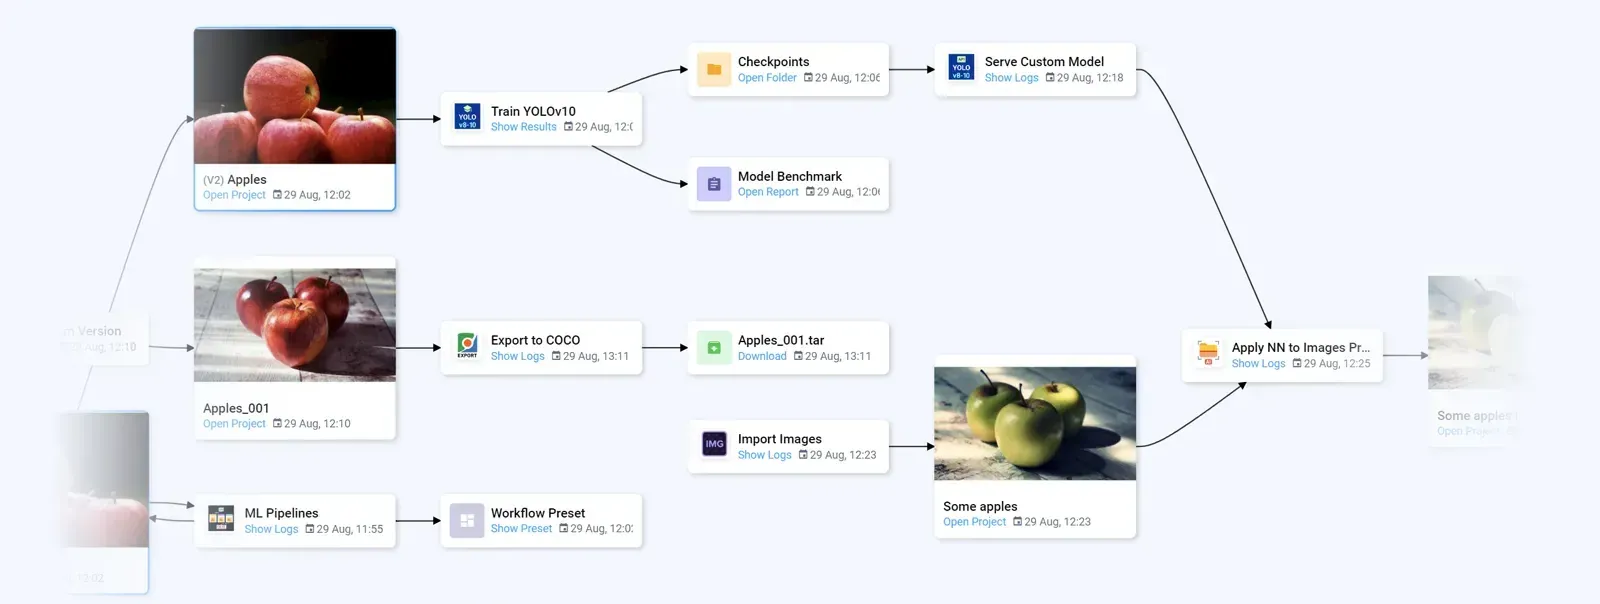 Part of an MLOps workflow graph in Supervisely
Below: how the main approaches differ, why versioning matters in the label, train and evaluate loop, and how to set it up in Supervisely.
Why do you need dataset versioning and experiment tracking?
Building a model is a loop: label → train → evaluate. Teams upload raw data, annotators label it, engineers augment it and train a network. After reviewing the reports, the team collects and labels more data, and the cycle repeats. Annotation specialists, data engineers, ML researchers and managers all work in this loop.
-
Data evolves over time: As data changes, it's crucial to track how and when these changes occur to maintain model accuracy.
-
Avoid confusion after multiple iterations: With each cycle, it becomes harder to keep track of which datasets and models were used, which leads to errors.
-
Ensure reproducibility and collaboration: Without tracking, it's nearly impossible to reproduce results or share accurate insights with colleagues after a period of time.
Without versioning you re-upload data, keep duplicate projects "just in case" and guess when to make backups. Versioning replaces that with one numbered history.
Which dataset versioning approach should you choose?
There is no single best tool. The right one depends on whether your team lives in Git or in a labeling platform. The facts below come from each tool's own pages.
| Approach | How it versions | Where the data lives | Best fit |
|---|---|---|---|
| Git LFS | Replaces large files with small text pointers in the repository | A remote server such as GitHub | Teams that already work in Git and need to version files. GitHub warns above 50 MiB, blocks regular files above 100 MiB and sets LFS file limits of 2 GB (Free, Pro), 4 GB (Team) and 5 GB (Enterprise Cloud) |
| DVC (Apache 2.0) | Stores data in a cache and remote, commits small .dvc files to Git (how it works) | Your own remote: S3, Azure, Google Cloud, SSH and others | Code-first teams that want pipelines and experiments inside a Git repository, with no server |
| MLflow Tracking (Apache 2.0) | Logs runs with parameters, metrics and artifacts. It can track datasets linked to training runs, but its docs do not describe it as dataset versioning | Local folder or a tracking server | Experiment tracking for any ML code, next to a data versioning tool |
| Supervisely project versions and MLOps Workflow | Versions are created in the UI on the Versions tab. The Workflow graph links versions to apps, training runs and reports | Inside the platform, media linked and not duplicated | Teams that label, train and review in one place. Needs the Pro or Enterprise plan |
How to read the table:
- Git LFS and DVC work on files. They are free and fit code-centric teams well. DVC also covers pipelines and experiments, which Git LFS does not. They do not know what a class, a tag or an annotation is, so a change is a changed file.
- MLflow answers "which run gave which metric". Pair it with a data versioning tool.
- Supervisely is annotation-aware: its version comparison report covers datasets, items, annotations, tags, classes and project settings. The trade-off is that you work inside the platform and need a paid plan. If your whole stack is Git and scripts, DVC may be the simpler choice.
How does dataset versioning work in Supervisely?
Each project has a dedicated Versions tab.
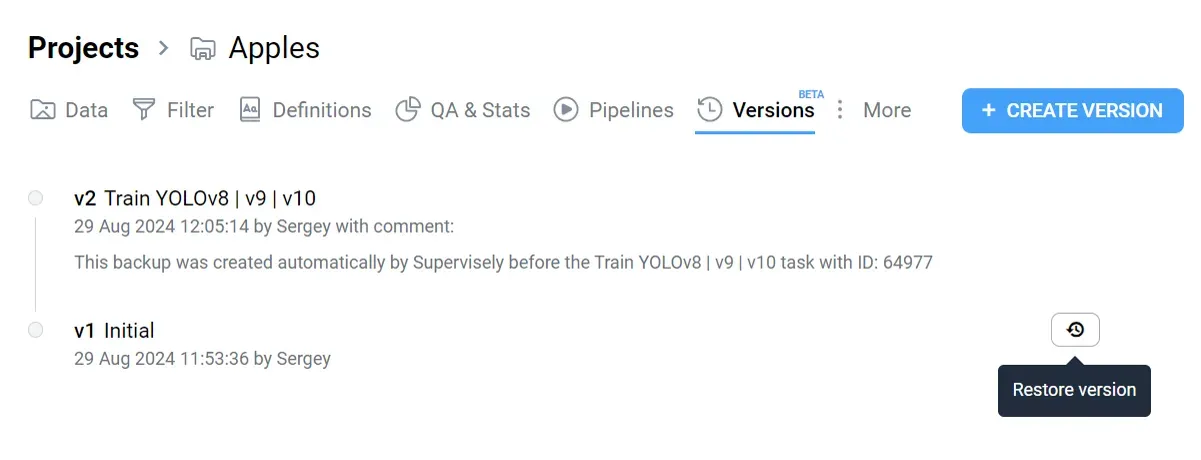 Project Versions tab
It lets you:
- Create and track versions. Create a version at upload, after annotation or after a transformation. A version can be created only if the project has changed since the last one. Titles and descriptions can be edited at any time.
- Store data efficiently. Versions are stored in a binary format. Media files are linked, not duplicated.
- Restore with a click. Restoring creates a separate project that reflects the selected version. The original project is not changed.
- Compare two versions. The report covers datasets, items, annotations, tags, classes and project settings, and can be downloaded as HTML. It needs Supervisely 6.18.3 or later and the Data Versioning app v0.4.0 or later. It describes changes but does not show images side by side, and it cannot compare a version with the current unsaved state. Use previews to look at the data itself.
Versions work for Images, Videos and Volumes projects. Read the Project Versions docs for details.
Pro and Enterprise users of the platform. See pricing.What is an MLOps Workflow and how does it track data evolution?
The MLOps Workflow is a graph that shows how your data moves through apps and operations. It also works as a version history, so you can trace where a change came from.
You can open it from three places: the context menu of a project, a task or a workspace.
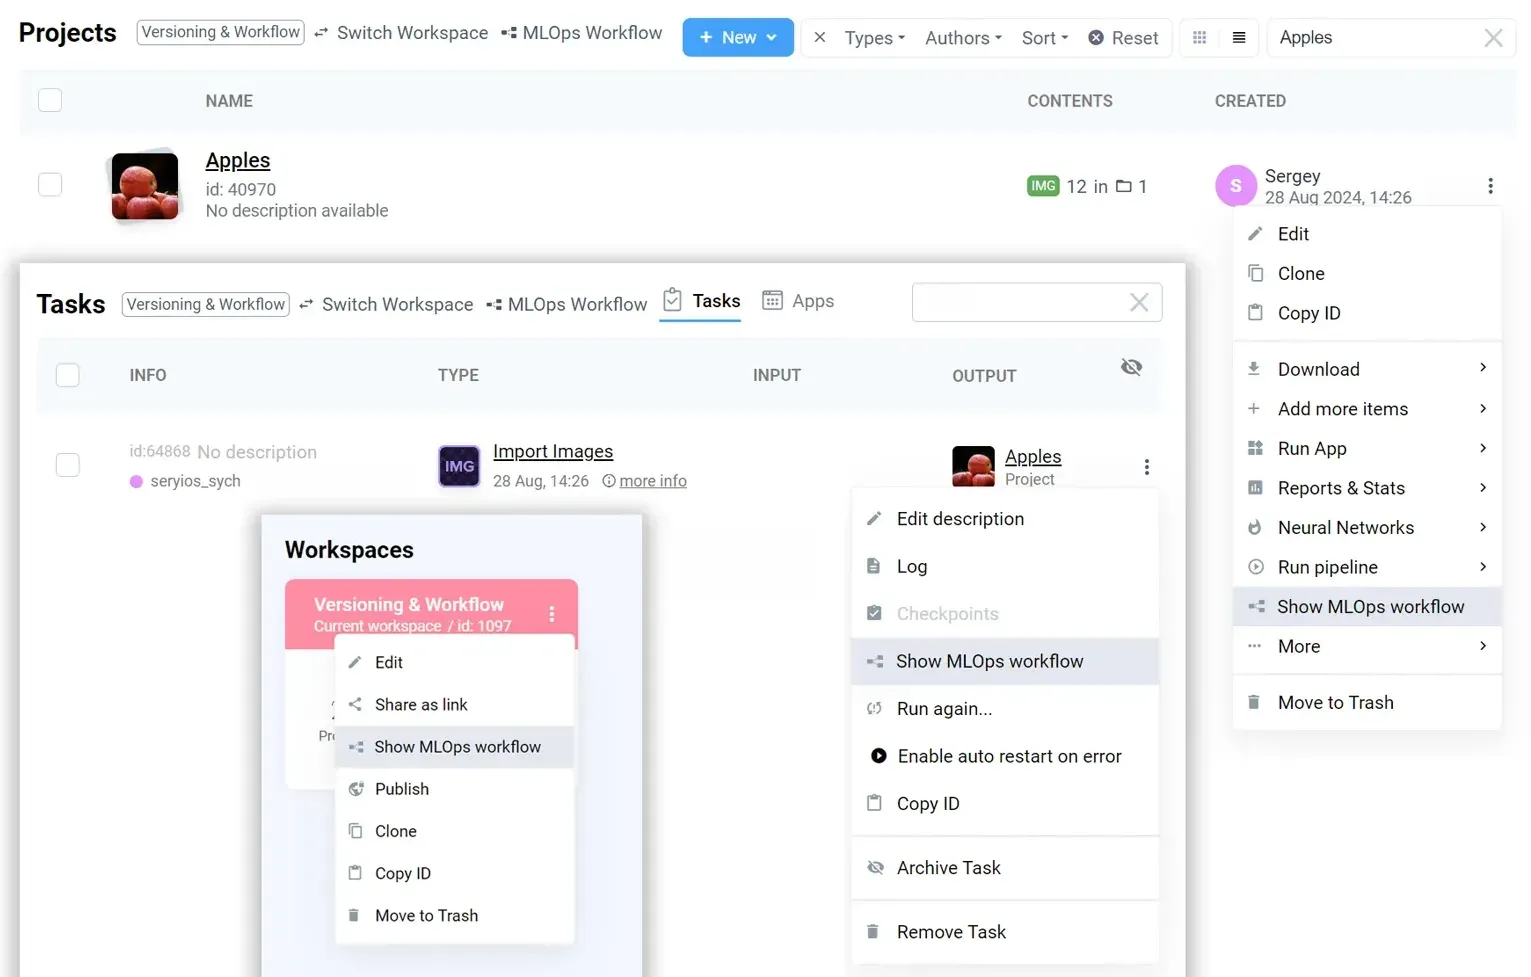 Entry Points into the Workflow
Operations you can see in the graph include:
- Creating version backups and restoring them
- Data augmentation: cropping, resizing, rotation, blurring, adding noise
- Labeling and tagging data
- Transforming annotations: converting shapes, merging, rasterizing
- Converting popular formats to and from Supervisely
- Splitting, merging, subsampling and filtering datasets
- Generating training data
The project lifecycle starts with data import. After that you can open the Workflow right away.
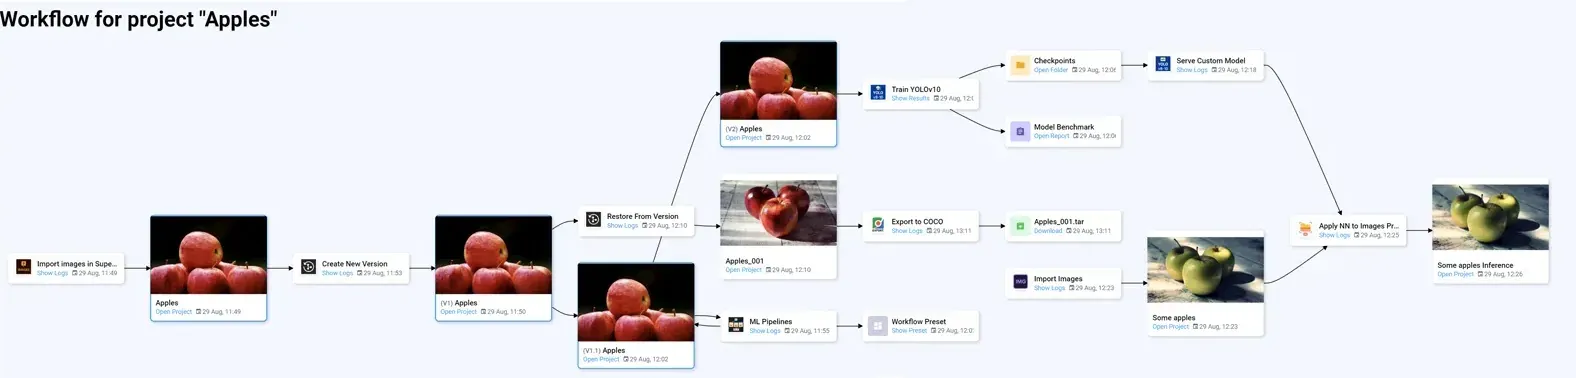 Workflow example
An example from the graph above:
- Data was labeled in the Image Labeling Tool with the Smart Tool and Segment Anything Model 2.
- Version v1 captured that state before data changes in ML Pipelines. The graph shows an intermediate state (v1.1) and a preset file from ML Pipelines, which lets you replay the same process on another project.
- Training with a Train app created version v2 automatically and produced checkpoints and benchmark reports.
- The trained model was applied to new datasets. A team member exported v1 in COCO format for collaborators on other platforms.
Minor versions such as v1.1 appear when the project changes after a major version. Only major versions can be restored.
How do you track experiments and compare models?
Training runs land on the Experiments page. Per the Experiments docs, each run keeps the model and task, the training dataset and image counts, hyperparameters, environment details, metrics, an evaluation report, TensorBoard logs, checkpoints and result files. Select several runs to open their evaluation reports side by side or to compare training metrics. You can also fine-tune an old run or train a new one with the same settings.
The model benchmark report shows metrics such as mAP, Precision, Recall, IoU, Classification Accuracy, Calibration Score and Inference Speed. Reviewing these across versions shows whether a change in data, architecture or hyperparameters helped.
How do you set up a versioned workflow step by step?
What you need: a Supervisely project on the Pro or Enterprise plan, and the latest platform and SDK versions. Supervisely can be deployed in the cloud or on-premise, see Enterprise.
- Create a version on the Versions tab after upload.
- Label, augment, split or convert the data with apps.
- Run a Train app. It creates a version and logs the run on the Experiments page.
- Open the Workflow from the project, task or workspace menu.
- Compare two versions, or restore one to a new project.
Teams that need to scale labeling can see labeling jobs and dataset quality assurance, and for slicing datasets before training see advanced dataset filters.
How do you add Workflow to your own apps?
To use the Workflow in custom applications, work with the latest platform and SDK versions and follow the MLOps Workflow Integration guide on the Developer Portal.
Best practices for readable workflows:
- Leverage projects over datasets: use project cards instead of one card per dataset.
- Use folder cards for archives: replace multiple File cards with a single Folder card for related work, and name the source folder in team Files after the task.
- Add descriptions: use the description fields in the customization settings.
- Change main node titles only when needed, for example to mark a special operating mode.
- Customize cards accurately: each card should contain precise information about its task.
- Do not overwrite card states: keep a clear history of connections.
- Organize session-based apps to prevent clutter around single tasks.
Frequently asked questions
What is dataset versioning in computer vision?
Dataset versioning means saving named states of your images and annotations, so you can restore an earlier state, compare two states and know which version a model was trained on. In computer vision the annotations change as often as the images do.
Is Git LFS enough to version a computer vision dataset?
Git LFS stores large files outside the Git history and keeps small pointers in the repository, so it works for files. It does not track experiments and it does not understand classes or annotations. Hosting limits also apply, for example GitHub blocks regular files above 100 MiB and caps LFS files at 2 GB on the Free plan.
What is the difference between DVC and Supervisely project versions?
DVC is an open-source command-line tool that keeps data in a cache and remote storage and versions small .dvc pointer files in Git. Supervisely project versions are created in the platform UI on the Versions tab, cover images, videos and volumes, and are linked to apps, training runs and reports in the MLOps Workflow graph. Versions need the Pro or Enterprise plan.
What is an ML experiment tracker?
An experiment tracker records every training run with its parameters, metrics, logs and output files, so runs can be compared and reproduced. MLflow Tracking is a well-known open-source example. In Supervisely the Experiments page records the model, dataset, hyperparameters, metrics, checkpoints and logs of each run.
Can I restore an old version of a Supervisely project?
Yes. Restoring creates a separate project that matches the selected version. The original project is not changed. Only major versions can be restored, not the minor ones shown between them in the Workflow.
Can I run this on my own servers?
Supervisely can be deployed in the cloud or on-premise. See the Enterprise page for the editions.


