Model training in Supervisely Blog
Custom Interactive Segmentation Model: Train It on Your Images
Train a custom click-based segmentation model (RITM) on your own images with no code. Benchmark on plant images: 18 minutes vs 66 for SAM and 190 by hand.
 Grigoriy Mananian

Semi-Supervised Learning: Train a Model with 62 Labeled Images
Semi-supervised HRDA on 62 labeled and 2,222 unlabeled images reached 0.6271 mIoU vs 0.7354 for a model trained on 11,110 labels. Setup and results.
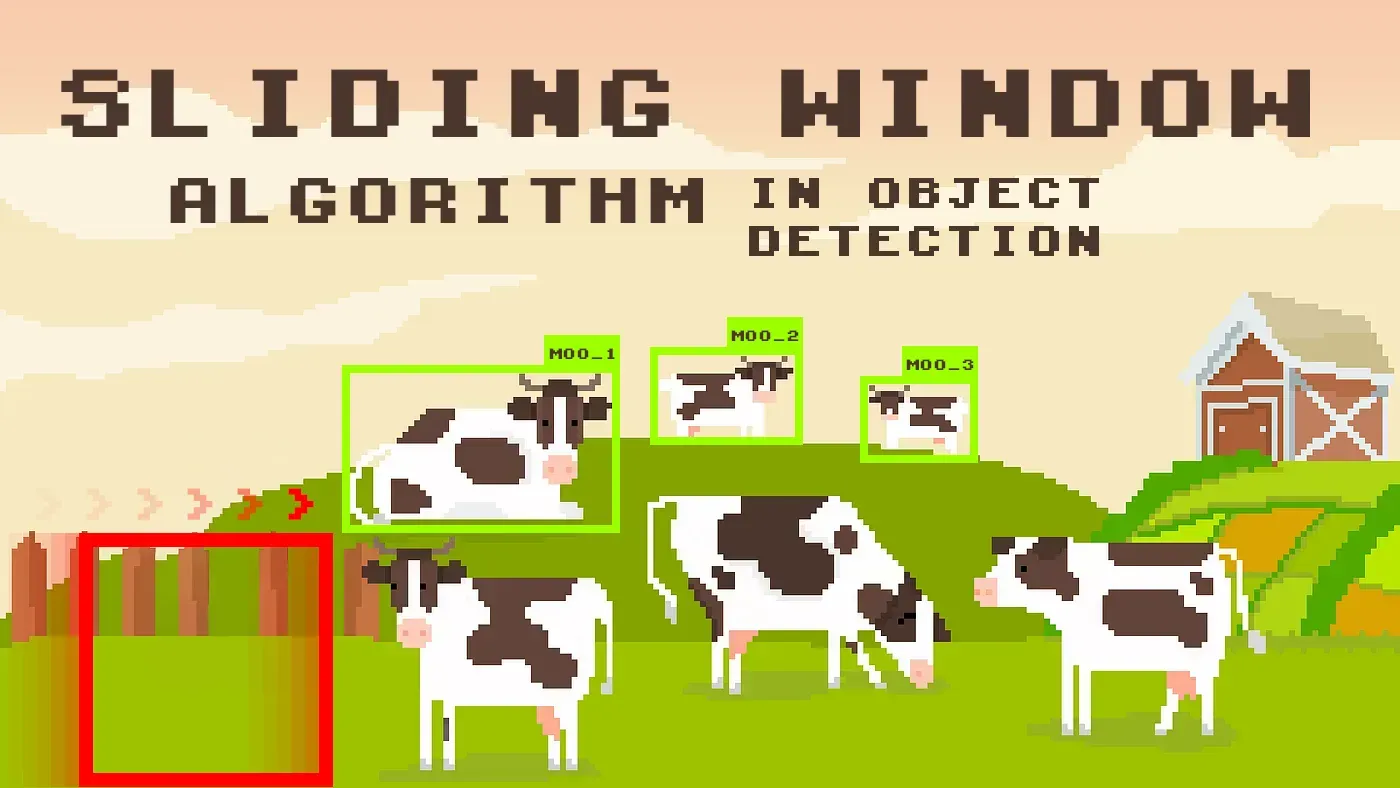
Sliding Window Object Detection: How It Works, SAHI vs Sliding Window
Sliding window inference runs a detector on overlapping tiles of a large image to find small objects. Learn how it works, SAHI vs sliding window, and setup.

Domain Adaptation with HRDA: Train on Synthetic Data
Train a crack segmentation model on synthetic images plus unlabeled real photos with HRDA domain adaptation. Data, setup, 20,000-iteration run, results.

Synthetic Data for Segmentation: 7 Steps That Improved Our Model
What we learned training dozens of segmentation models on synthetic cracks: seven data steps, from edge smoothing to style transfer, that narrowed the gap.

Pose Estimation Models: Human and Animal Pose Estimation Explained
What pose estimation is, which models to pick (OpenPose, HRNet, ViTPose, RTMPose, YOLO pose) and how to label keypoints for people and animals in Supervisely.
OCR Text Detection with MMOCR: How It Works and How to Run It
OCR text detection finds where text is in an image, recognition reads it. See how MMOCR does both and how to run it in Supervisely to pre-label text fast.

Animal Pose Estimation: Models, Datasets and How to Label Animals
Animal pose estimation finds keypoints on pets, livestock and wildlife. See which datasets and models exist, and how to label animal keypoints in Supervisely.

ViTPose Tutorial: Run ViTPose and Auto-Label Poses in Supervisely
ViTPose explained and step by step: deploy pretrained ViTPose checkpoints for humans and animals, pre-label keypoints, and run it with YOLOv8 on a full dataset.
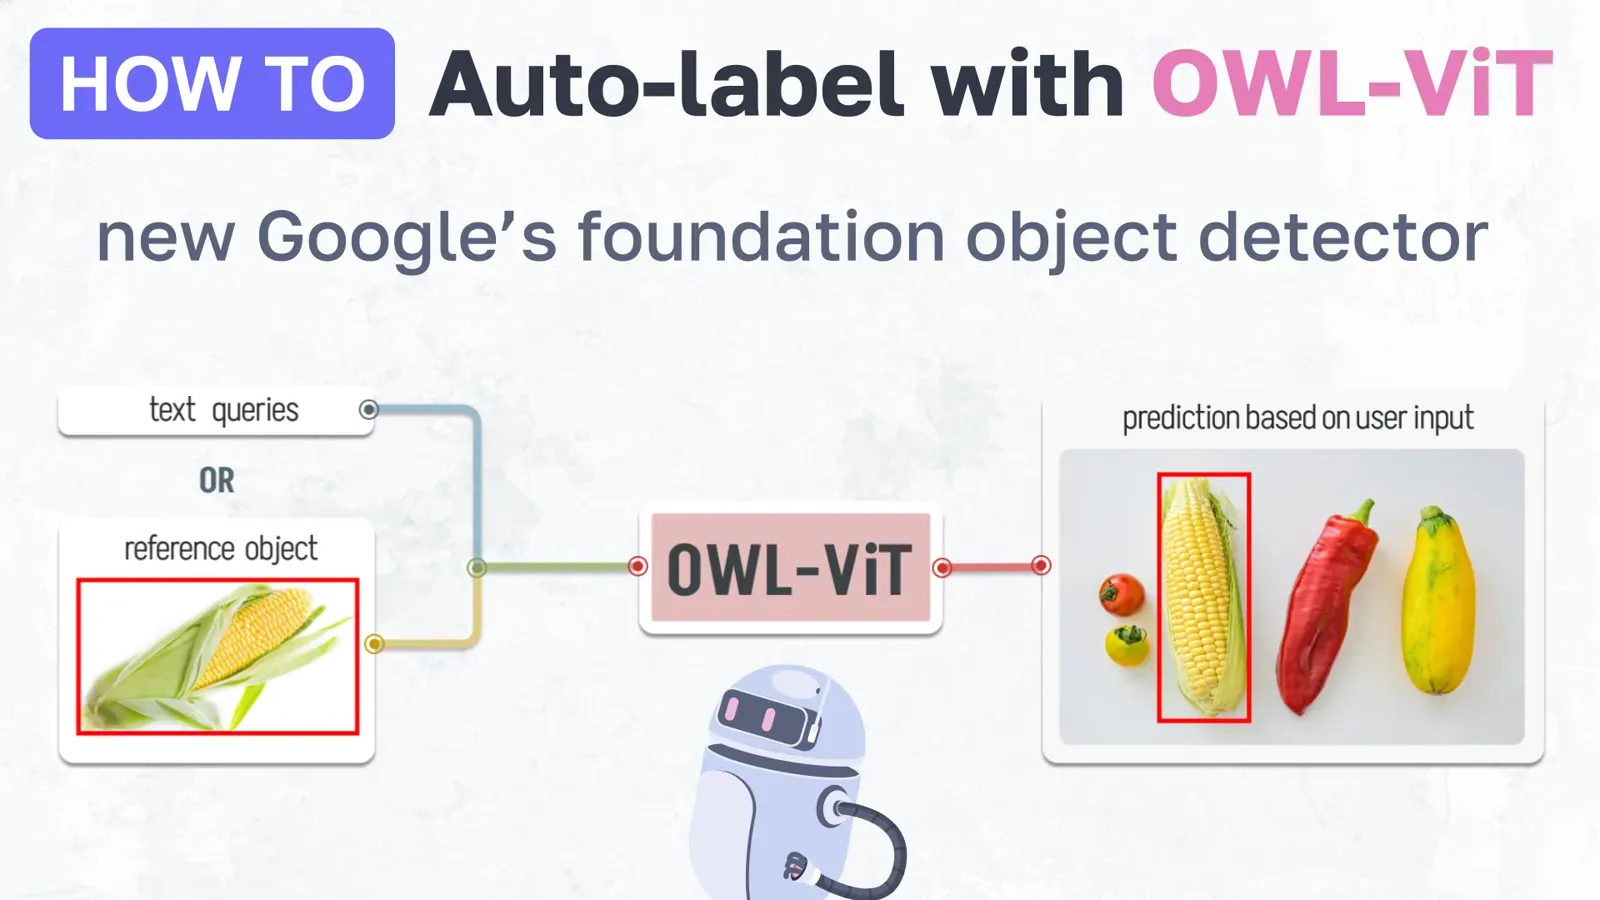
OWL-ViT Few-Shot Object Detection: Auto-Label Images With One Example
OWL-ViT finds objects from a text prompt or a single reference box. See how to run it in Supervisely and pre-label a whole dataset on your own GPU.
How to Train YOLOv8 on Custom Data Without Code
Train YOLOv8 on your own dataset in the browser: prepare data, connect a GPU, train, deploy and pre-label images with no code. With demo data.